Integrations fail. What matters is whether you catch it in seconds or find out days later.
An order fails to sync on Monday, and nobody notices until a customer calls on Thursday. Every integration fails sometimes, but silent failures are the ones that hurt.
We set up Celigo’s error tools, retries, alerts and dashboards. Problems get detected right away and resolved quickly, and the same failure stops coming back.
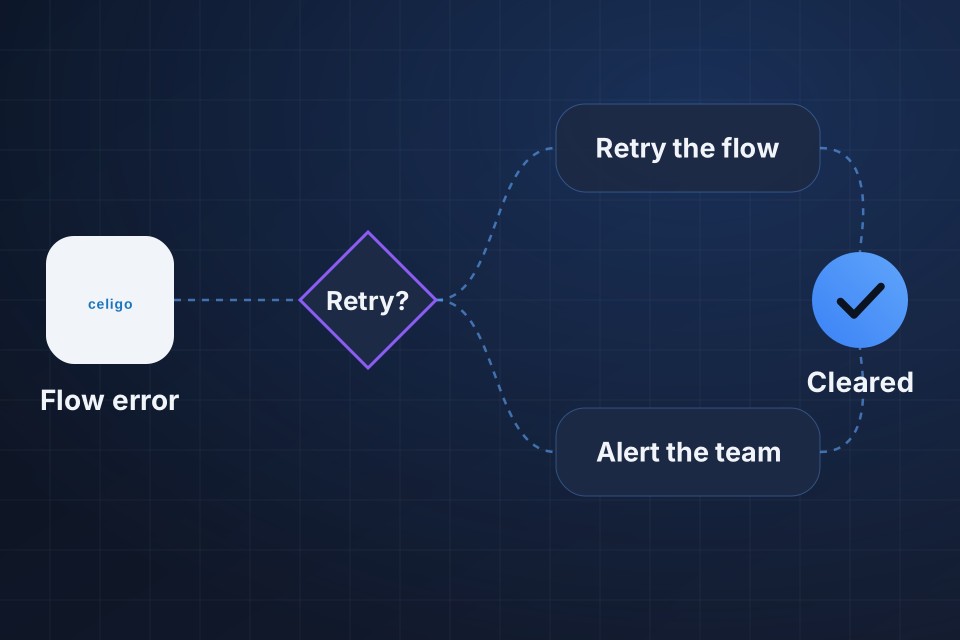
Automatic retries for errors that clear on their own
Errors sorted by type and routed to the right person
Real-time alerts by email, Slack or PagerDuty
Dashboards and audit trails for every error
We go through your error history and flows to see what fails, how often and who finds out.
We group errors by type and separate short-lived failures from the ones a person must fix.
We add retries, flow-level throttling and auto-resolution rules, then route whatever is left to the right people.
We set alerts for odd data volumes, delays and lost connections, and build dashboards your team can work from.
We bring deep Celigo integration experience and understand how to build reliable, scalable integration systems. Error handling is a big part of that reliability, so we treat it as a core piece of your platform.
Celigo saves each failed record, with details of the error, in its dashboard. We set the retry rules, error types and fix steps so your team can clear issues fast.
Yes. We watch for odd data volumes, slow processing and lost connections, which catches trouble before it turns into failed transactions or data gaps.
We configure flow-level throttling and retry logic that respect the limit. Celigo’s queue-based design then absorbs the slowdown when an outside system can’t keep up.
Yes, many types can with the right configuration. We build retry logic for short-lived errors and auto-resolution rules for known error patterns, which cuts manual work significantly.
Tell us about your project and we'll get back to you within 24 hours.